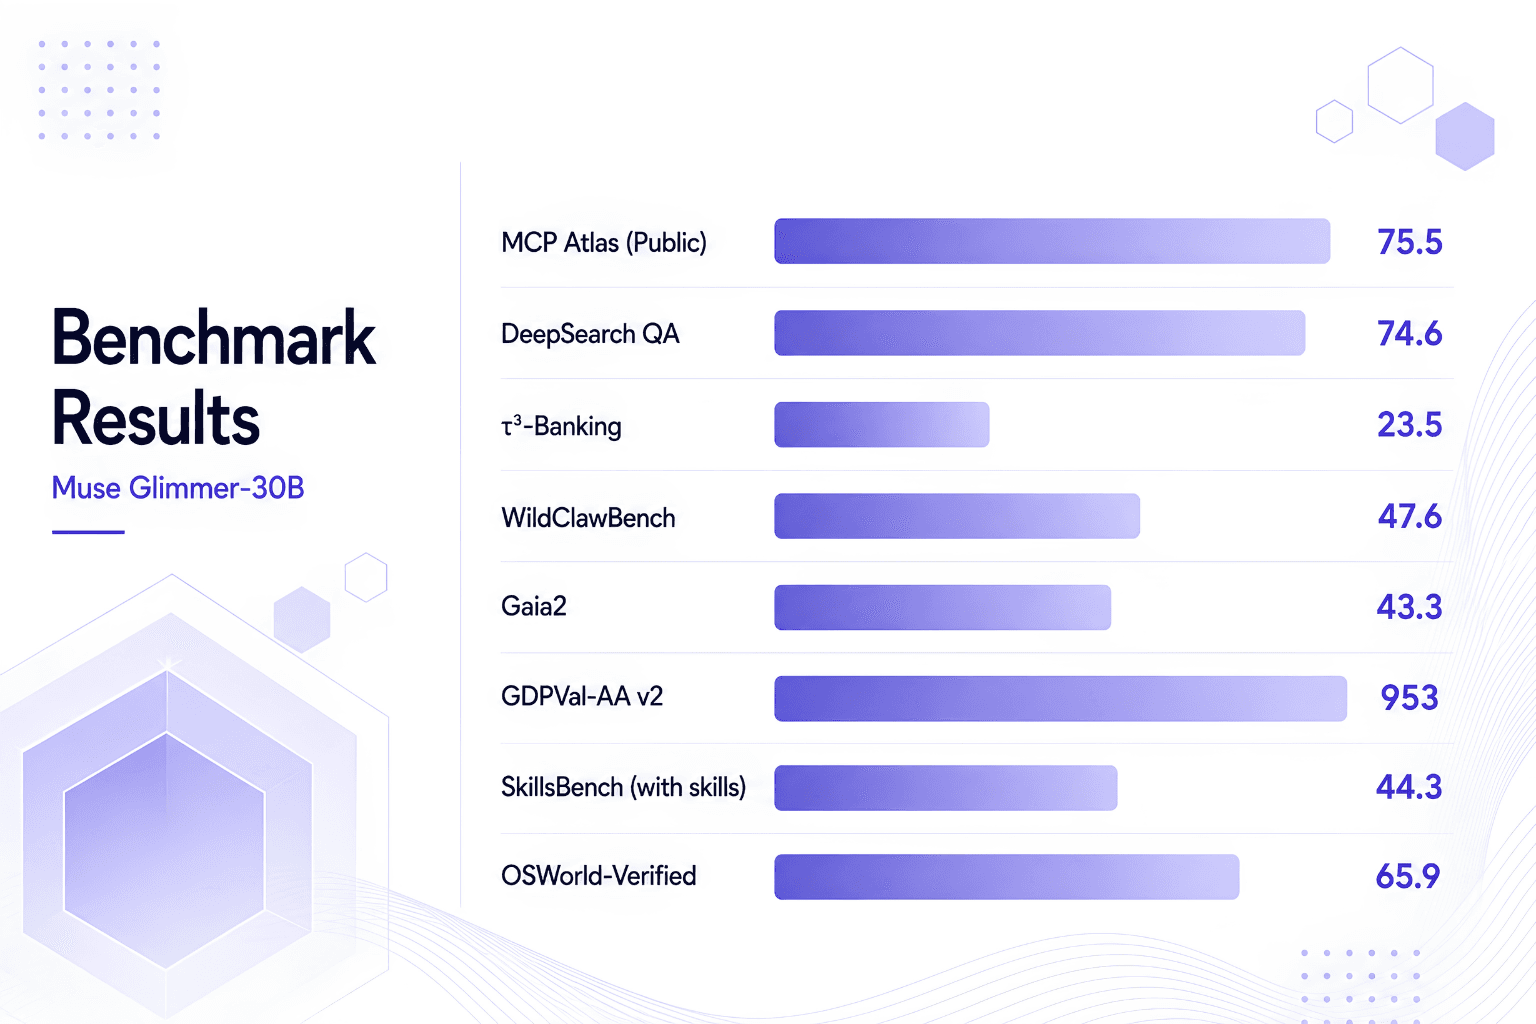
Muse Glimmer Benchmarks: Official and Independent Results
Every published Muse Glimmer benchmark: MCP Atlas 75.5, SWE-Bench Pro 51.2, AIME 94.7, Artificial Analysis Intelligence Index 35, plus where the model loses
Stay updated with the latest news and insights from Qubrid AI.

September 3, 2026
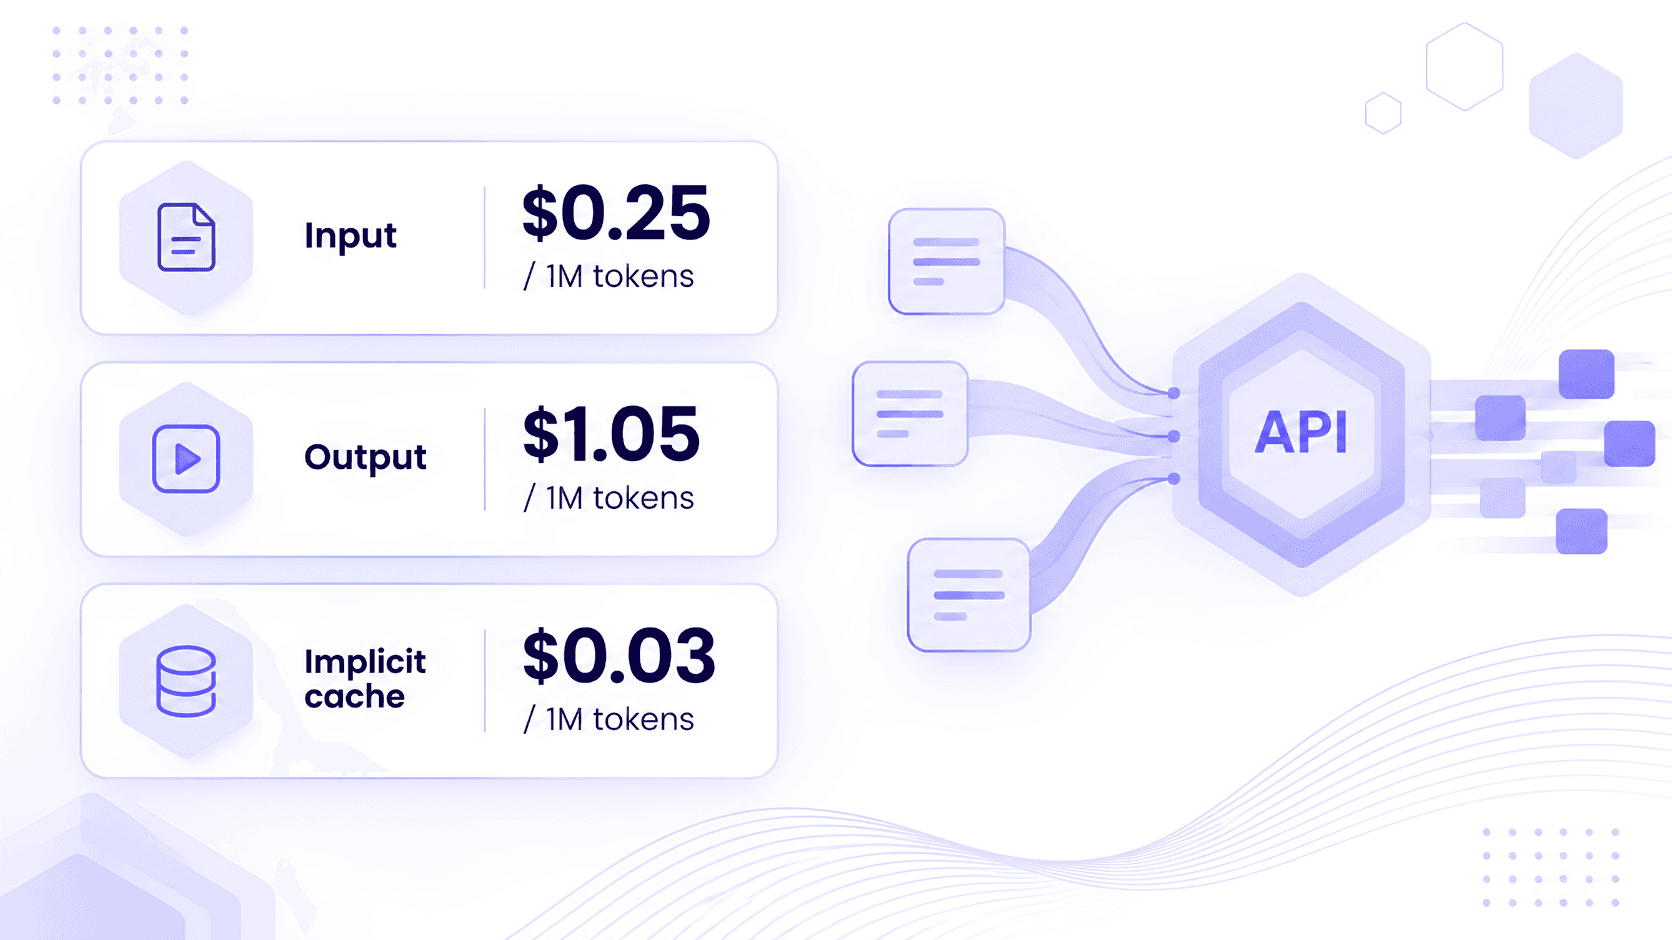
Muse Glimmer costs $0.25 per 1M input tokens and $1.05 per 1M output on Qubrid AI, with an 88% cache discount. Cost math, and when self-hosting wins instead

Every published Muse Glimmer benchmark: MCP Atlas 75.5, SWE-Bench Pro 51.2, AIME 94.7, Artificial Analysis Intelligence Index 35, plus where the model loses

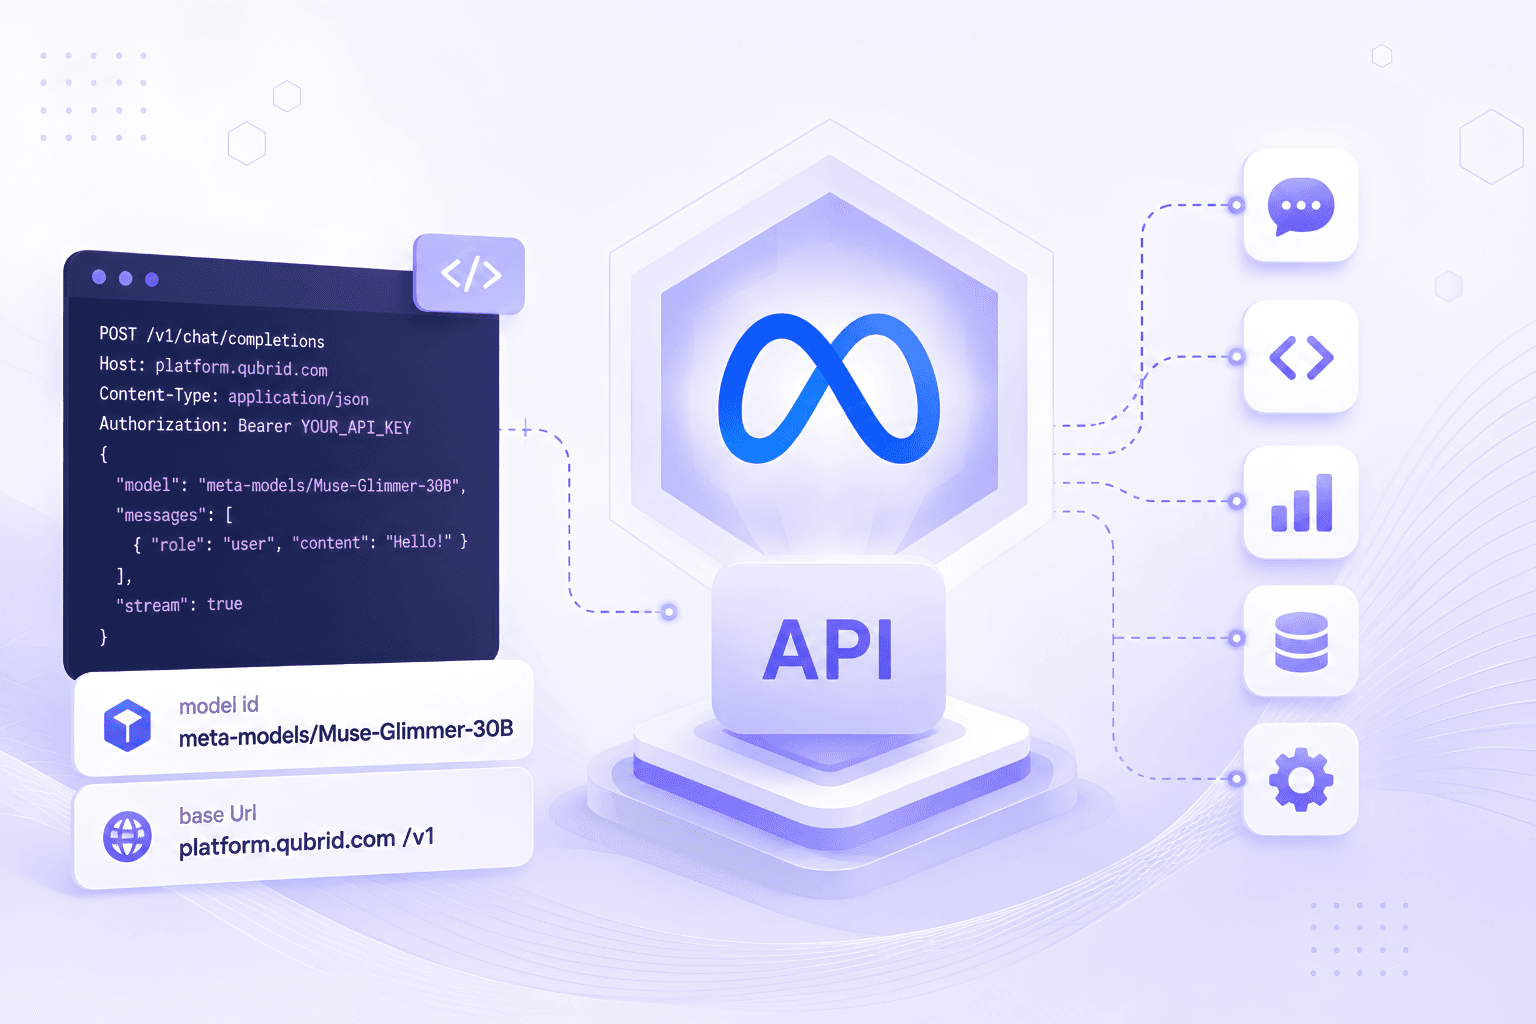
Call the Meta Muse Glimmer API on Qubrid AI's OpenAI-compatible endpoint. Setup, reasoning strength, vision input, tool calling, sampling, and troubleshooting

Complete Meta Muse Glimmer guide: official and independent benchmarks, API pricing at $0.25/1M input tokens, architecture, hardware specs, and production code

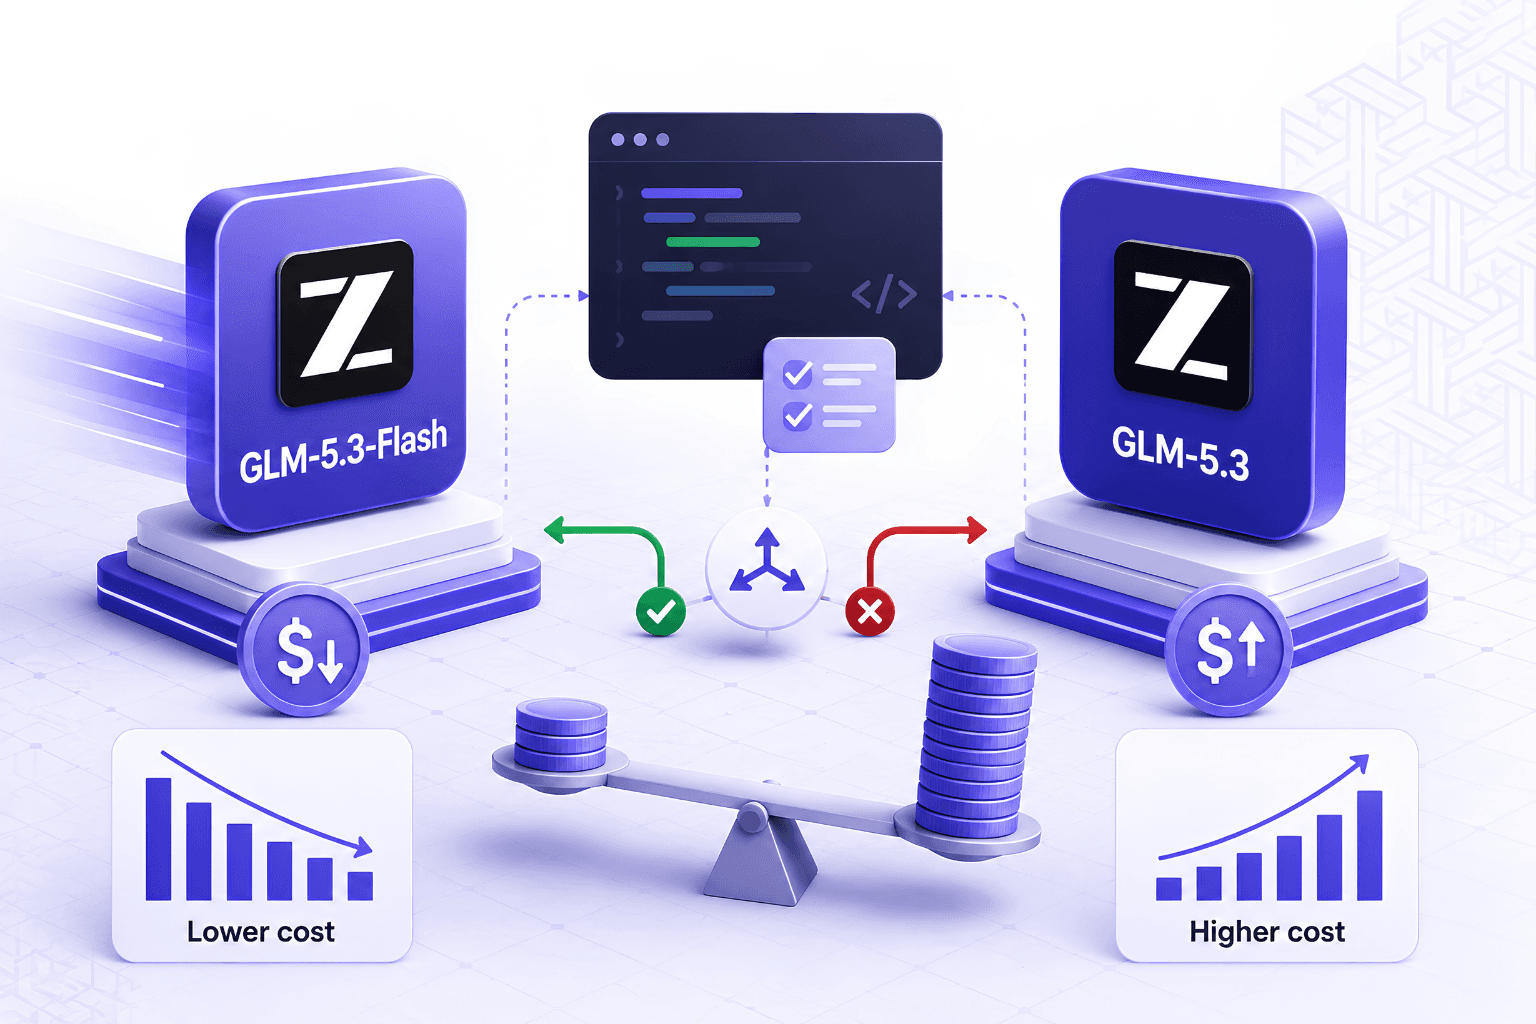
GLM-5.3 scores 66.9 on DeepSWE, Flash scores 63.4, on an identical harness. The real question is cost per solved task, and a cascade beats both on that metric

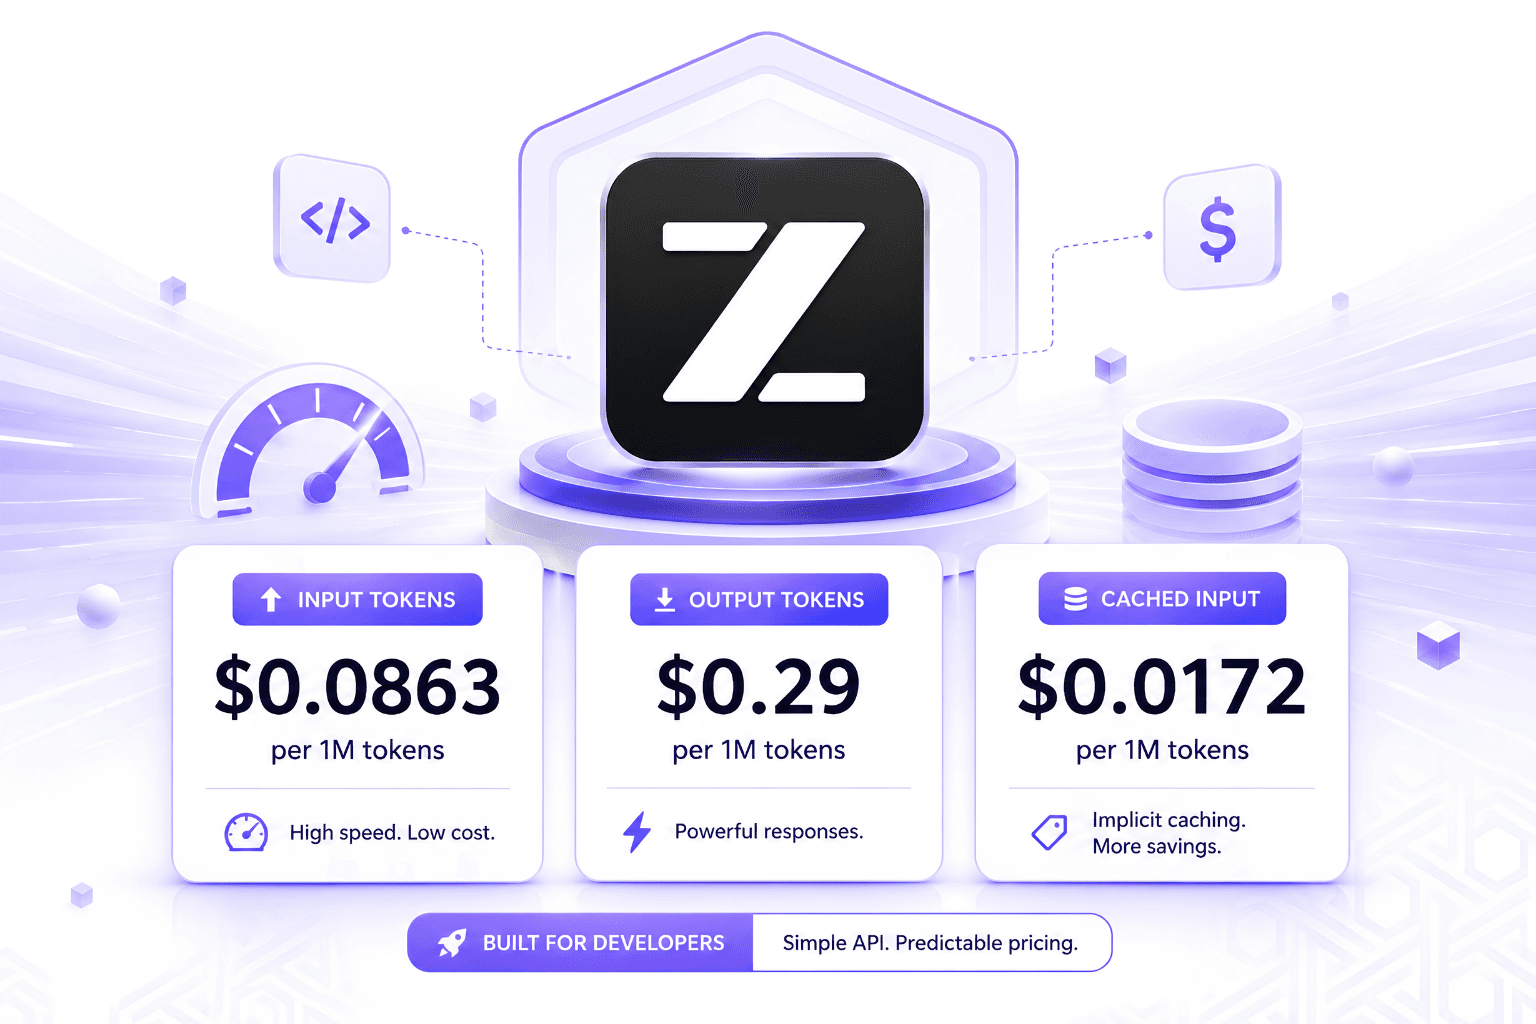
GLM-5.3-Flash costs $0.0863 per 1M input tokens and $0.29 per 1M output on Qubrid AI. Cache pricing, reasoning-token cost math, and self-hosting break-even

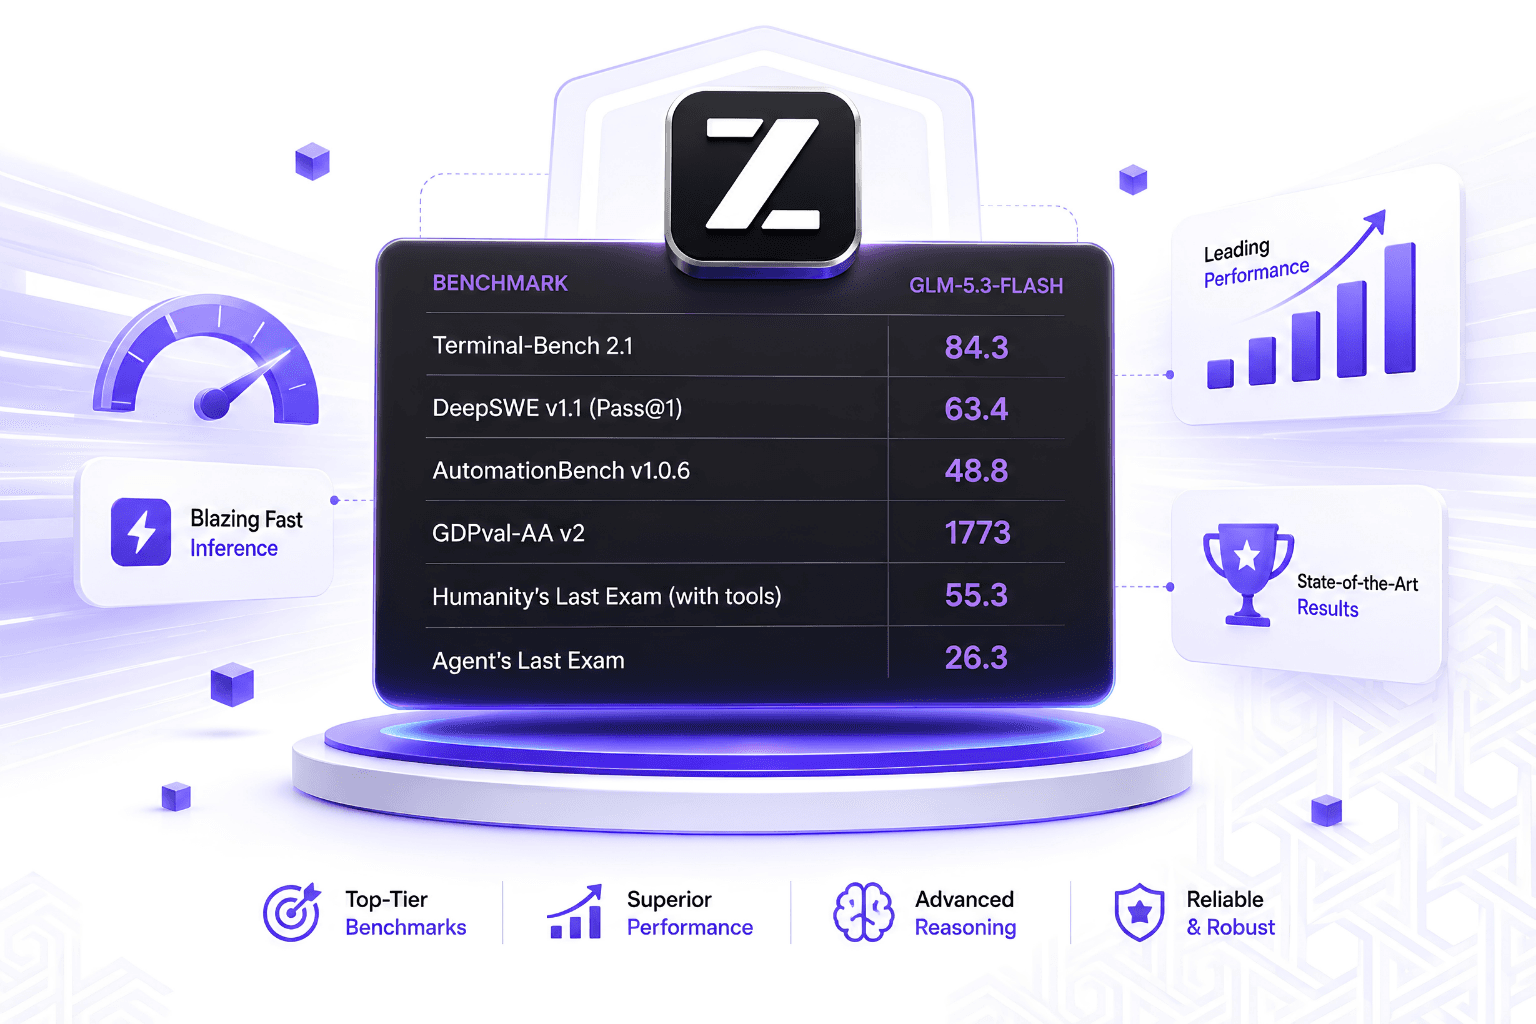
Every published GLM-5.3-Flash benchmark: Terminal-Bench 84.3, DeepSWE 63.4, Artificial Analysis Intelligence Index 57, ExtractBench, and methodology caveats

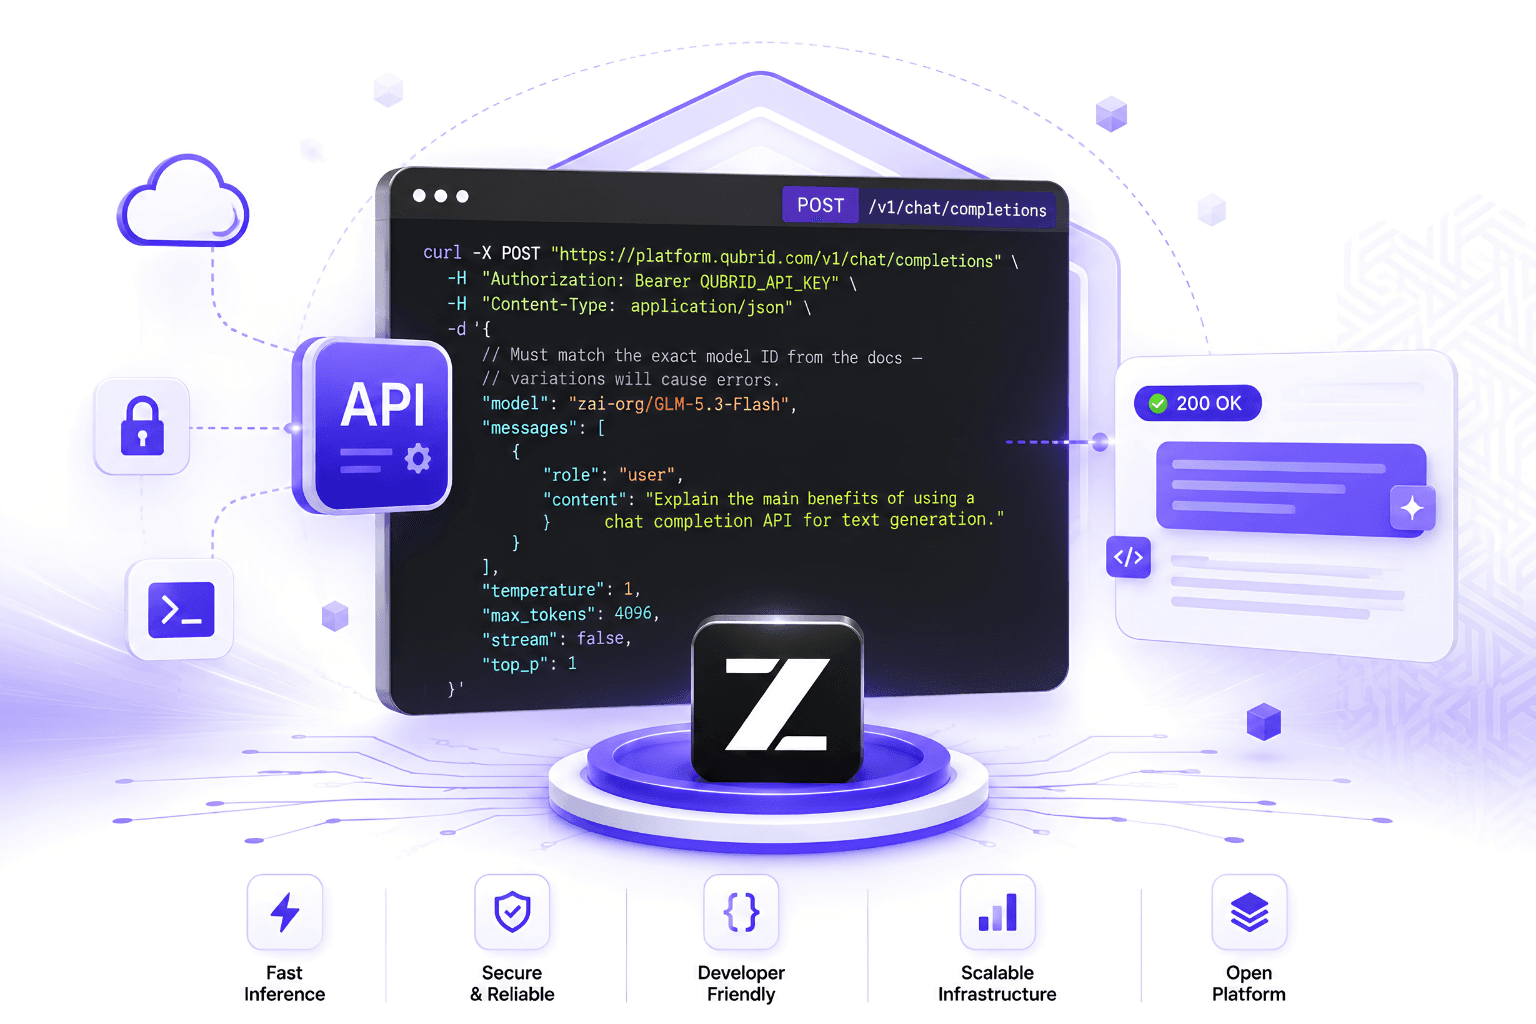
Call the GLM-5.3-Flash API on Qubrid AI's OpenAI-compatible endpoint. Setup, reasoning_effort control, vision and video input, streaming, and troubleshooting

Complete GLM-5.3-Flash guide: independently verified benchmarks, API pricing at $0.0863/1M input tokens, hybrid attention architecture, and production code