Last updated Sep 3, 2026.
Muse Glimmer Benchmarks: Official and Independent Results
9 minutes read

Shubham Tribedi
Quick answer: Muse Glimmer scores 35 on the Artificial Analysis Intelligence Index, ranking 5th of 140 open-weight models in its size class against a class median of 9. Meta's own evaluation puts it at 75.5 on MCP Atlas, 51.2 on SWE-Bench Pro and 94.7 on AIME 2026. It wins 12 of 22 rows in Meta's own comparison against Gemma4-31B and Qwen3.6-27B, and loses 10. This page publishes both halves.
The shape of the results, up front
Muse Glimmer is a 30-billion-parameter dense multimodal model distilled from Muse Spark and released under Apache 2.0 in August 2026. Meta built it for local agentic work, and its benchmark profile reflects that with unusual clarity.
The pattern that runs through everything below: it leads decisively on agentic orchestration and trails on raw capability measures. That is not a flaw in the model, it is the shape of what Meta optimised for. Knowing which side of that line your workload sits on is worth more than any single score.
Official benchmarks: agentic
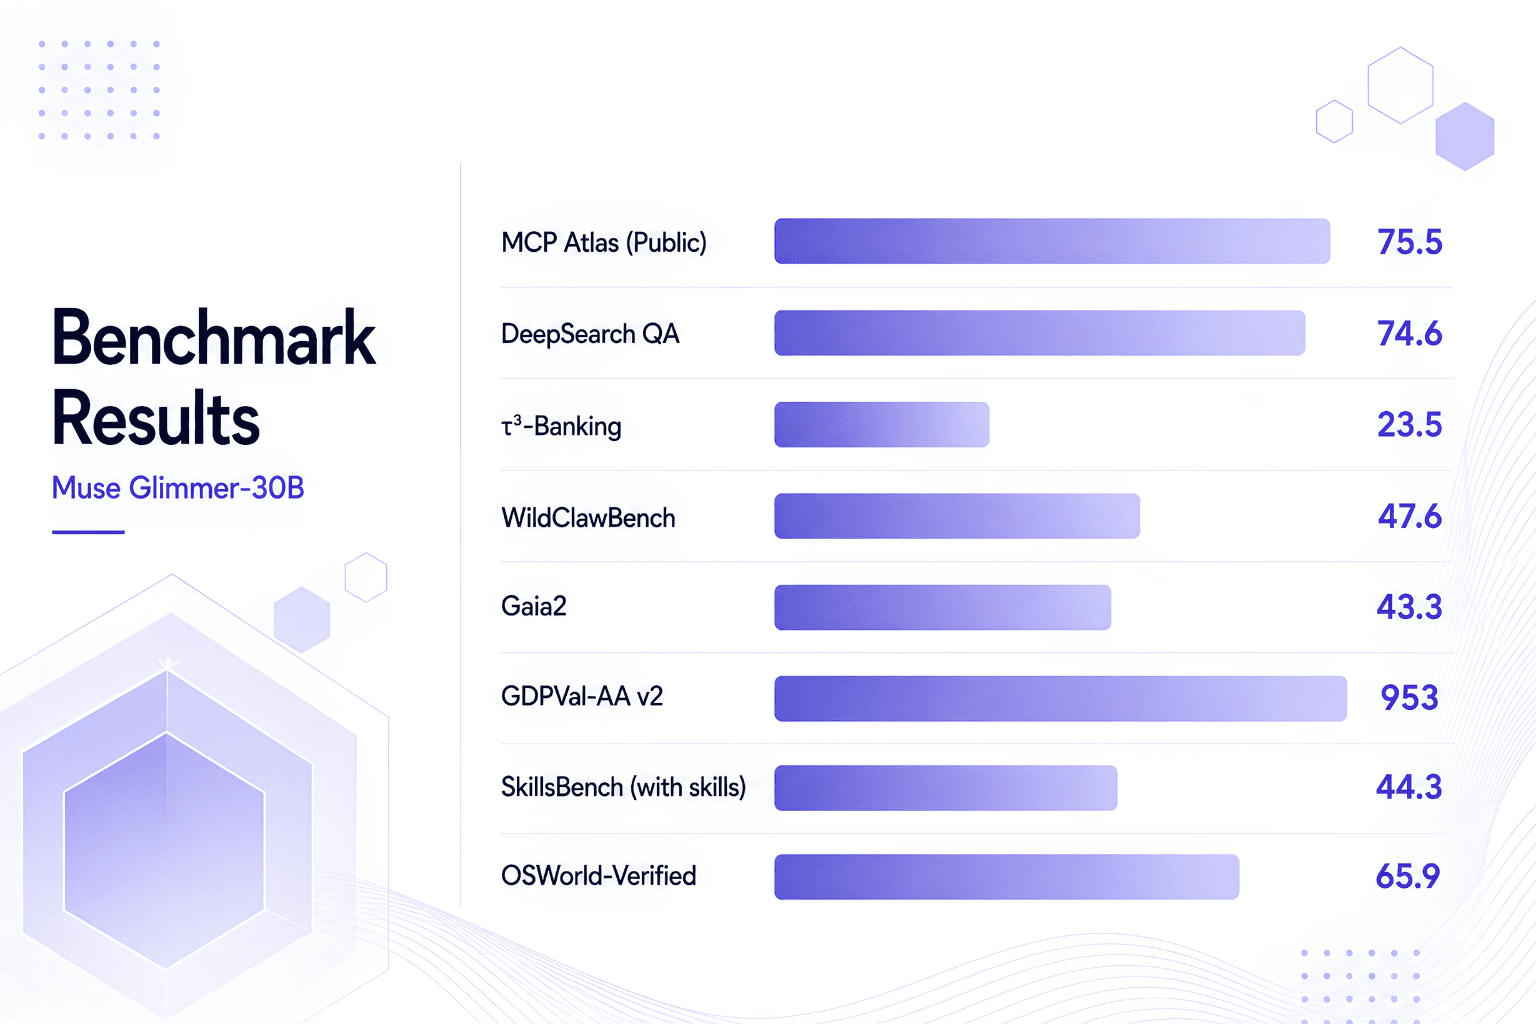
From the Muse Glimmer model card, comparing Muse Glimmer at high reasoning against Gemma4-31B and Qwen3.6-27B, both in thinking mode.
Benchmark | Muse Glimmer-30B | Gemma4-31B | Qwen3.6-27B |
|---|---|---|---|
MCP Atlas (Public) | 75.5 | 54.2 | 62.5 |
DeepSearch QA | 74.6 | 61.7 | 71.1 |
τ³-Banking | 23.5 | 15.1 | 16.7 |
WildClawBench | 47.6 | 37.6 | 43.2 |
Gaia2 | 43.3 | 36.4 | 40.0 |
GDPVal-AA v2 | 953 | 811 | 1141 |
SkillsBench (with skills) | 44.3 | 32.4 | 46.6 |
OSWorld-Verified | 65.9 | 58.5 | 75.6 |
MCP Atlas at 75.5 against 62.5 for the nearest competitor is a 13-point margin, the widest in the entire comparison. τ³-Banking at 23.5 against 16.7 is proportionally larger still, roughly 41% higher than the next model.
These benchmarks measure whether a model can drive a multi-step workflow through tools without losing the thread. That is what Meta trained for, and the results are unambiguous.
The three losses in this section are equally informative. OSWorld-Verified at 65.9 against Qwen3.6-27B's 75.6 is a near-10-point gap on computer use. GDPVal-AA v2 at 953 against 1141 is a wide margin on real-world work tasks.
Official benchmarks: agentic coding
Benchmark | Muse Glimmer-30B | Gemma4-31B | Qwen3.6-27B |
|---|---|---|---|
SWE-Bench Pro | 51.2 | 36.9 | 50.2 |
SWE-Bench Verified | 76.0 | 66.6 | 77.2 |
TerminalBench 2.1 (with terminus2) | 51.7 | 43.4 | 60.7 |
SciCode | 43.6 | 43.4 | 39.8 |
A split result, and the split is worth understanding. Muse Glimmer takes SWE-Bench Pro, the harder variant, by a single point. It loses SWE-Bench Verified by 1.2 points and TerminalBench 2.1 by 9.
The TerminalBench gap is the one to weigh. If your coding agent lives in a terminal running commands, that 9-point deficit is material and you should benchmark alternatives on your own tasks.
Official benchmarks: multimodal
Benchmark | Muse Glimmer-30B | Gemma4-31B | Qwen3.6-27B |
|---|---|---|---|
CharXiv Reasoning | 78.8 | 77.7 | 78.4 |
ScreenSpot Pro | 75.4 | 75.9 | 76.1 |
OmniDocBench v1.5 | 75.8 | 72.5 | 77.8 |
MMMU Pro | 74 | 73 | 75 |
All four rows land within about two points across all three models. Muse Glimmer's ~1.8B parameter ViT-G/14 perception encoder puts it squarely in the pack rather than ahead of it.
The practical read: vision is a genuine capability here rather than a differentiator. If multimodal accuracy is your primary criterion, these four rows will not decide it for you.
Official benchmarks: general reasoning
Benchmark | Muse Glimmer-30B | Gemma4-31B | Qwen3.6-27B |
|---|---|---|---|
IFBench | 77.0 | 76.0 | 70.8 |
AIME 2026 | 94.7 | 89.2 | 94.1 |
AA-LCR | 80.0 | 68.3 | 73.3 |
Beam128K | 65.1 | 58.2 | 63.0 |
GPQA Diamond (AA) | 83.5 | 85.7 | 84.2 |
HLE Text (AA) | 22.0 | 23.6 | 23.1 |
AA-LCR at 80.0 against 68.3 and 73.3 is the standout, an 11.7-point margin over the next model on long-context reasoning. Beam128K repeats the pattern. For a model shipping a 131,072-token window, being strongest exactly there is the right kind of consistency.
AIME 2026 at 94.7 is the highest absolute score in the whole table.
The two losses are both knowledge-heavy: GPQA Diamond and Humanity's Last Exam. A 30B model distilled for agentic behaviour is not where you go for breadth of world knowledge.
Independent benchmarks: Artificial Analysis
Artificial Analysis evaluated Muse Glimmer at high reasoning strength, which gives an outside check on Meta's own numbers.
Metric | Muse Glimmer (high) | Class median | Rank in class |
|---|---|---|---|
Intelligence Index | 35 | 9 | #5 of 140 |
Output speed | 108.9 tok/s | 100.9 | #31 of 140 |
Time to first token | 0.79s | 2.04s | - |
Output tokens across index | 48M | 48M | #16 of 140 |
Intelligence Index v4.1.1 is a nine-evaluation composite: GDPval-AA v2, τ³-Banking, Terminal-Bench v2.1, SciCode, Humanity's Last Exam, GPQA Diamond, CritPt, AA-Omniscience and AA-LCR.
On the 35. That is well above the class median of 9 and places Muse Glimmer fifth among 140 open-weight models in the 4B-to-40B band. Read the comparison class carefully: this is a ranking within small open-weight models. Larger flagship models score substantially higher, and a headline like "35" means nothing without the class attached to it.
The latency figure is the most under-reported number in this release. A 0.79-second time to first token against a 2.04-second class median is roughly 2.6x better than typical. For an agent making dozens of sequential tool calls in a single session, per-call latency compounds in a way that per-token throughput simply does not. A model that starts responding in under a second changes how a long agent loop feels far more than one that finishes a paragraph slightly faster.
Conciseness has a commercial edge. 48M output tokens across the index sits exactly at the median, which Artificial Analysis rates as fairly concise. Since reasoning tokens bill as output, a model that reasons efficiently costs less to run than its headline per-token price implies.
Where Muse Glimmer loses, in one place
Vendor blog posts rarely publish this table. It is the most useful one here.
Benchmark | Muse Glimmer | Better model | Gap |
|---|---|---|---|
OSWorld-Verified | 65.9 | Qwen3.6-27B, 75.6 | -9.7 |
TerminalBench 2.1 | 51.7 | Qwen3.6-27B, 60.7 | -9.0 |
GDPVal-AA v2 | 953 | Qwen3.6-27B, 1141 | -188 |
SkillsBench | 44.3 | Qwen3.6-27B, 46.6 | -2.3 |
GPQA Diamond | 83.5 | Gemma4-31B, 85.7 | -2.2 |
HLE Text | 22.0 | Gemma4-31B, 23.6 | -1.6 |
OmniDocBench v1.5 | 75.8 | Qwen3.6-27B, 77.8 | -2.0 |
SWE-Bench Verified | 76.0 | Qwen3.6-27B, 77.2 | -1.2 |
MMMU Pro | 74 | Qwen3.6-27B, 75 | -1 |
ScreenSpot Pro | 75.4 | Qwen3.6-27B, 76.1 | -0.7 |
Two of those gaps are large enough to change a decision: computer use and terminal-based coding. The rest are within a couple of points, which on most benchmarks is inside the range where run-to-run variance matters.
If your workload is GUI automation or a terminal-heavy coding agent, benchmark alternatives on your own tasks before committing. If it is tool-calling orchestration, long-context reasoning or instruction following, the wins are in the right column.
Methodology caveats you should actually read
These are Meta's evaluations of Meta's model against two competitors Meta selected. That is normal practice and it is still worth stating.
Comparison models ran in thinking mode and Muse Glimmer ran at high reasoning strength, which is a reasonable matching but not an identical one.
TerminalBench 2.1 was run with terminus2. Harness choice materially affects agentic coding scores.
GPQA Diamond, HLE Text and AA-LCR are labelled (AA) in Meta's table, indicating Artificial Analysis methodology rather than Meta's own harness.
AIME 2026 at 94.7 is near ceiling. Scores that high compress differences and make small gaps hard to interpret.
Meta states plainly that the model may produce inaccurate, biased or objectionable responses, and may still err in multi-step reasoning in novel scenarios. AA-Omniscience, one of the nine evaluations in the Intelligence Index, exists specifically to measure knowledge reliability and hallucination.
Security benchmarks, which almost nobody covers
Meta published security and privacy results alongside the capability numbers, and for a model built to run autonomous agents these arguably matter more than SWE-Bench.
Benchmark | Muse Glimmer-30B | Gemma4-31B | Qwen3.6-27B |
|---|---|---|---|
Siren AgentDojo, attack success rate (lower is better) | 28.4 | 25.6 | 40.3 |
Siren AgentDojo, utility | 94.2 | 90.8 | 92.7 |
CI Memories, violation rate (lower is better) | 26.4 | 12.1 | 53.4 |
CI Memories, coverage | 64.8 | 53.0 | 66.9 |
Muse Glimmer resists prompt injection better than Qwen3.6-27B by a wide margin and worse than Gemma4-31B by a small one, while retaining the highest utility of the three. On contextual-integrity memory violations it again sits between the two.
A 28.4% attack success rate is not a security guarantee. It means that in roughly one attempt in four, an adversarial injection succeeded. Any agent with real permissions needs scaffold-level defences and human confirmation for irreversible actions regardless of which model is behind it.
Frequently asked questions
What is Muse Glimmer's Intelligence Index score? 35 on the Artificial Analysis Intelligence Index at high reasoning strength, ranking 5th of 140 open-weight models in its size class against a class median of 9.
What does Muse Glimmer score on SWE-Bench? 51.2 on SWE-Bench Pro and 76.0 on SWE-Bench Verified, per Meta's evaluation.
What does Muse Glimmer score on AIME 2026? 94.7, the highest absolute score in Meta's comparison table and ahead of both Gemma4-31B at 89.2 and Qwen3.6-27B at 94.1.
Muse Glimmer vs Qwen3.6-27B: which is better? Depends entirely on workload. Muse Glimmer leads on MCP Atlas, DeepSearch QA, τ³-Banking, WildClawBench, Gaia2, SWE-Bench Pro, SciCode, IFBench, AIME, AA-LCR and Beam128K. Qwen3.6-27B leads on OSWorld-Verified, TerminalBench 2.1, GDPVal-AA v2, SkillsBench, SWE-Bench Verified, OmniDocBench, ScreenSpot Pro and MMMU Pro.
Muse Glimmer vs Gemma4-31B: which is better? Muse Glimmer wins the large majority of rows in Meta's comparison. Gemma4-31B leads on GPQA Diamond, HLE Text and the CI Memories violation rate.
Are Muse Glimmer's benchmarks independently verified? Partly. The Artificial Analysis Intelligence Index score of 35 is independent, and several rows in Meta's own table are labelled as using Artificial Analysis methodology. The agentic benchmarks are Meta's own runs.
How fast is Muse Glimmer? 108.9 tokens per second with a 0.79-second time to first token, per Artificial Analysis, against class medians of 100.9 and 2.04.
Is Muse Glimmer good at computer use? Less so than its size-class peers. OSWorld-Verified at 65.9 trails Qwen3.6-27B at 75.6 by nearly 10 points.
Is Muse Glimmer resistant to prompt injection? Partially. A 28.4% attack success rate on Siren AgentDojo is better than Qwen3.6-27B at 40.3 and worse than Gemma4-31B at 25.6. Treat scaffold-level guardrails as mandatory.
How verbose is Muse Glimmer? Fairly concise. 48M output tokens across the Artificial Analysis Intelligence Index, exactly at the class median.
Benchmark it yourself
meta-models/Muse-Glimmer-30B is live on Qubrid AI at $0.25 per 1M input tokens. Point any OpenAI-compatible SDK at https://platform.qubrid.com/v1, put Reasoning strength: high in your system prompt, and evaluate it on your own workload, which is the only benchmark that decides anything.