Qwen3.8-27B Pricing: API Cost per 1M Tokens
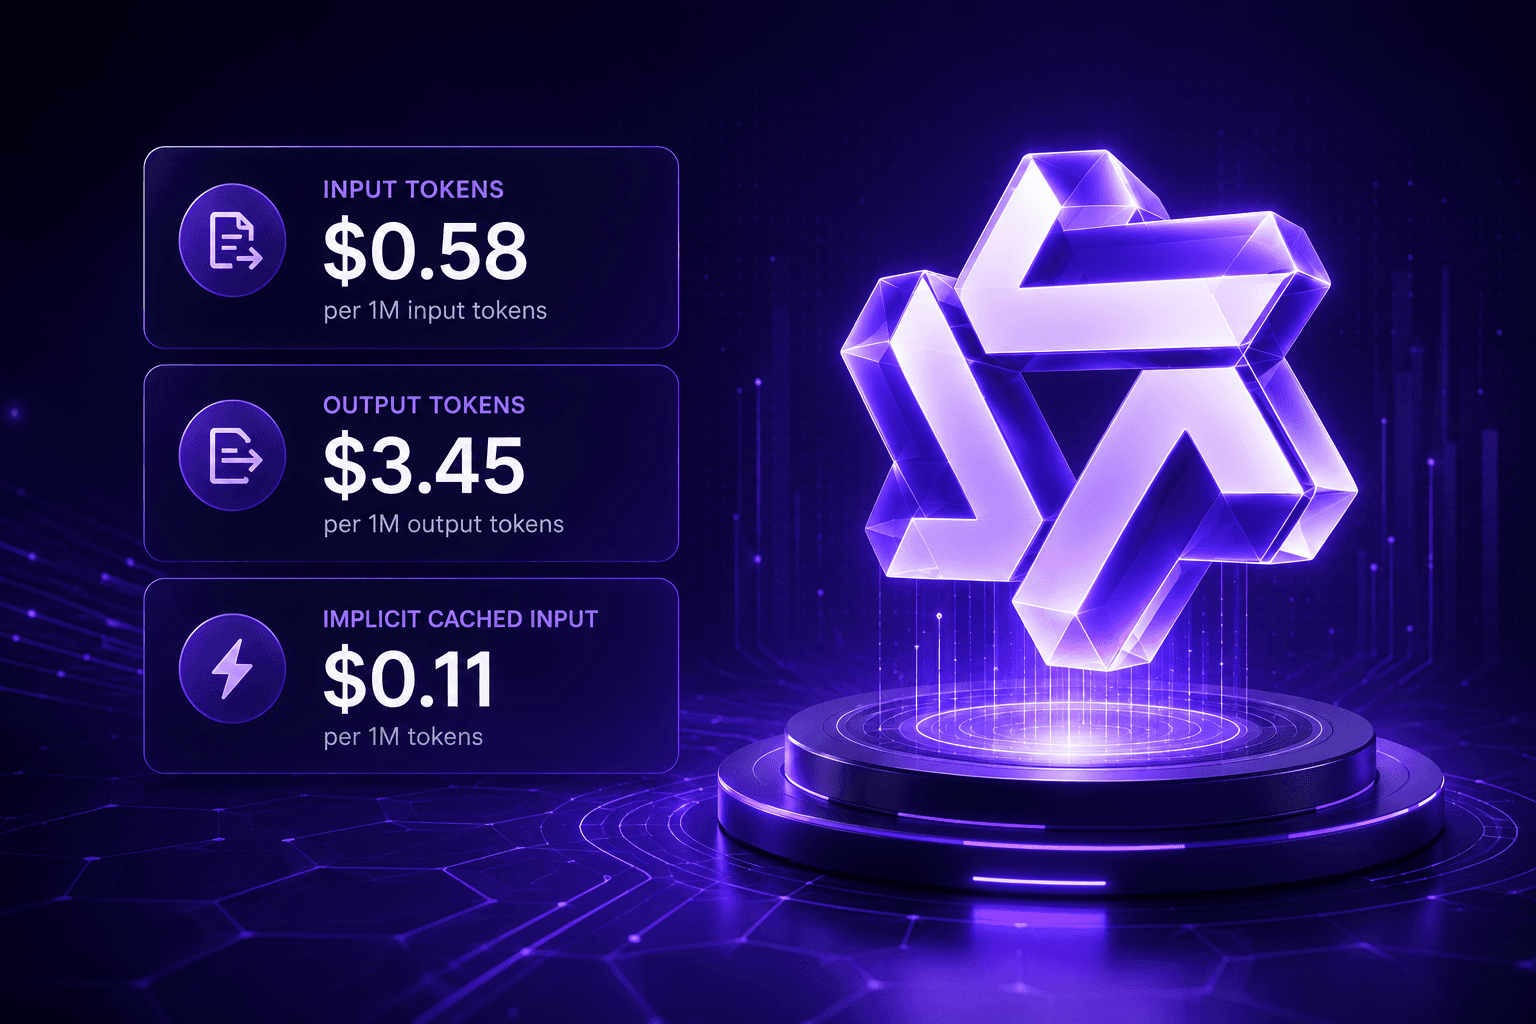
Qwen3.8-27B costs $0.58 per 1M input tokens and $3.45 per 1M output on Qubrid AI. Cache pricing, reasoning-token cost math, and API vs self-hosting break-even
Stay updated with the latest news and insights from Qubrid AI.

Qwen3.8-27B costs $0.58 per 1M input tokens and $3.45 per 1M output on Qubrid AI. Cache pricing, reasoning-token cost math, and API vs self-hosting break-even

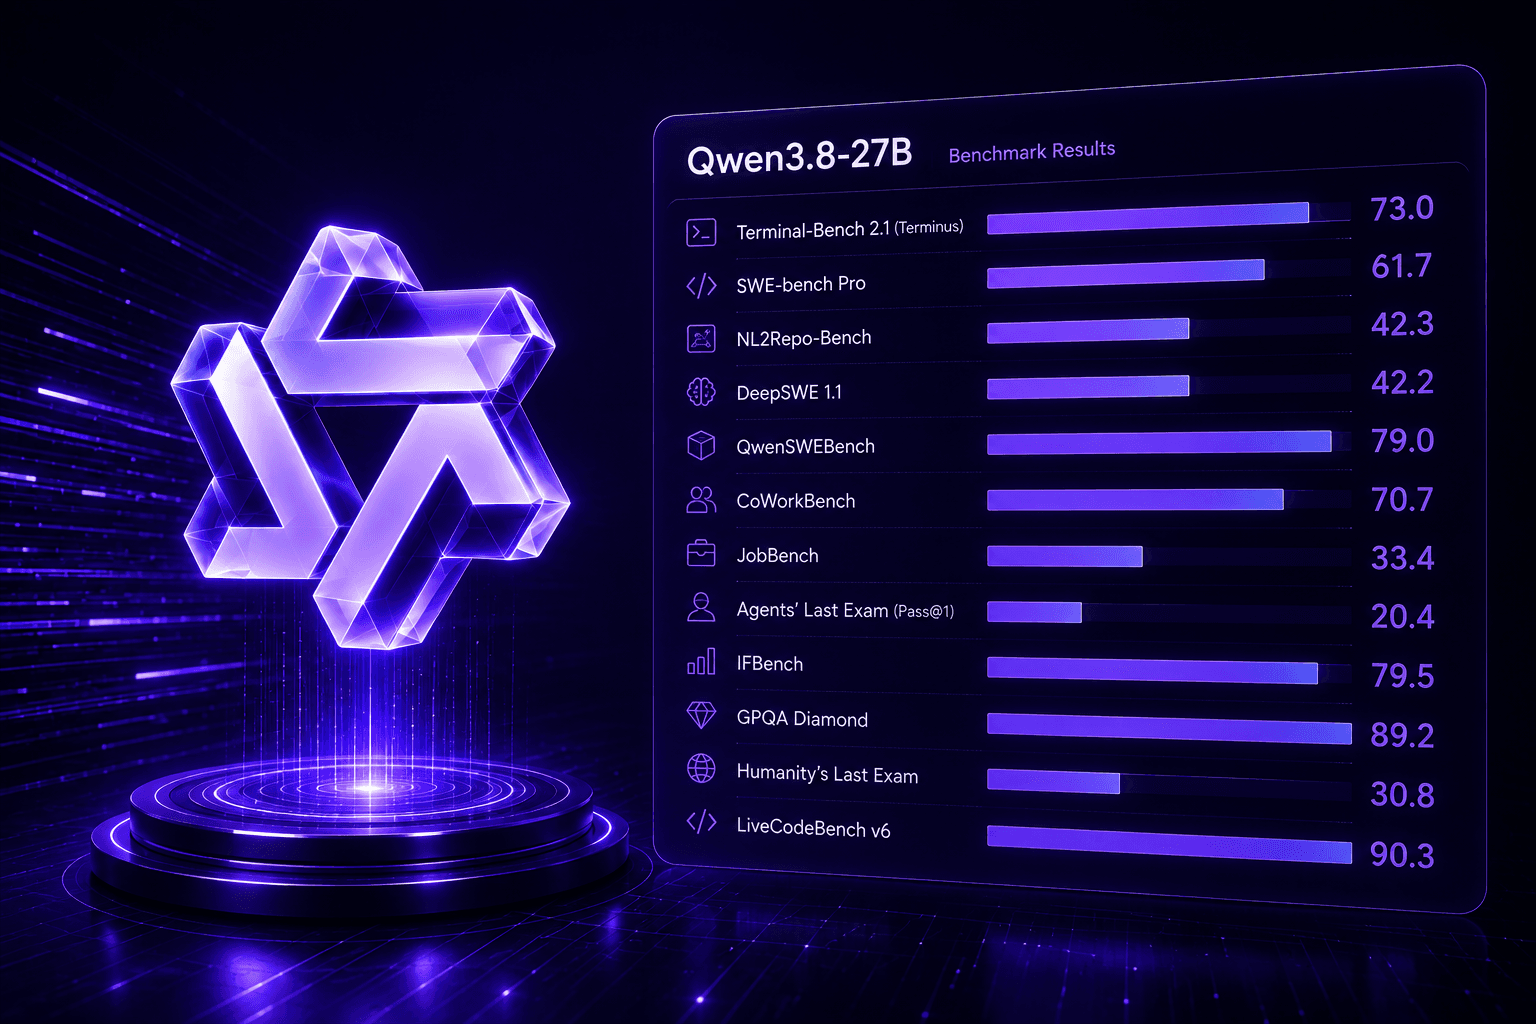
Every published Qwen3.8-27B benchmark in one place: SWE-bench Pro 61.7, OSWorld 84.3, Artificial Analysis Intelligence Index 52, and the methodology caveats

Call the Qwen3.8-27B API on Qubrid AI's OpenAI-compatible endpoint. Setup, streaming, vision input, reasoning_effort tuning, sampling parameters, and migration

Complete Qwen3.8-27B guide: official and independent benchmarks, API pricing at $0.58/1M input tokens, architecture, hardware requirements, and production code

We told you we were a GLM-5.3 launch partner. Access is now open, and GLM-5.3 is live on the Qubrid AI inference platform behind our OpenAI-compatible endpoint, at $1.61 per million input tokens, $5.06 per million output tokens, and $0.30 per million implicit-cache tokens - a 20% discount on list

Qubrid AI is a launch partner for GLM-5.3. We are working directly with the Z.ai team on the rollout. GLM-5.3 will be available on the Qubrid inference platform as soon as partner access opens

NVIDIA shipped Nemotron 3.5 Lightning on August 11, 2026. It is live on the Qubrid AI API today at $0.069 per million input tokens and $0.29 per million output tokens, with implicit caching at $0.0069 per million tokens.

Two of the largest open-weight models ever built shipped within eighteen days of each other.

Alibaba's 2.4-trillion-parameter flagship is available on Qubrid AI from day zero. Here is the full benchmark breakdown, the honest read on what the numbers mean, Qwen 3.8 Max pricing, and production-ready integration code.