
Last updated Aug 31, 2026.
Qwen3.8-27B Benchmarks: Official and Independent Results
9 minutes read

Shubham Tribedi
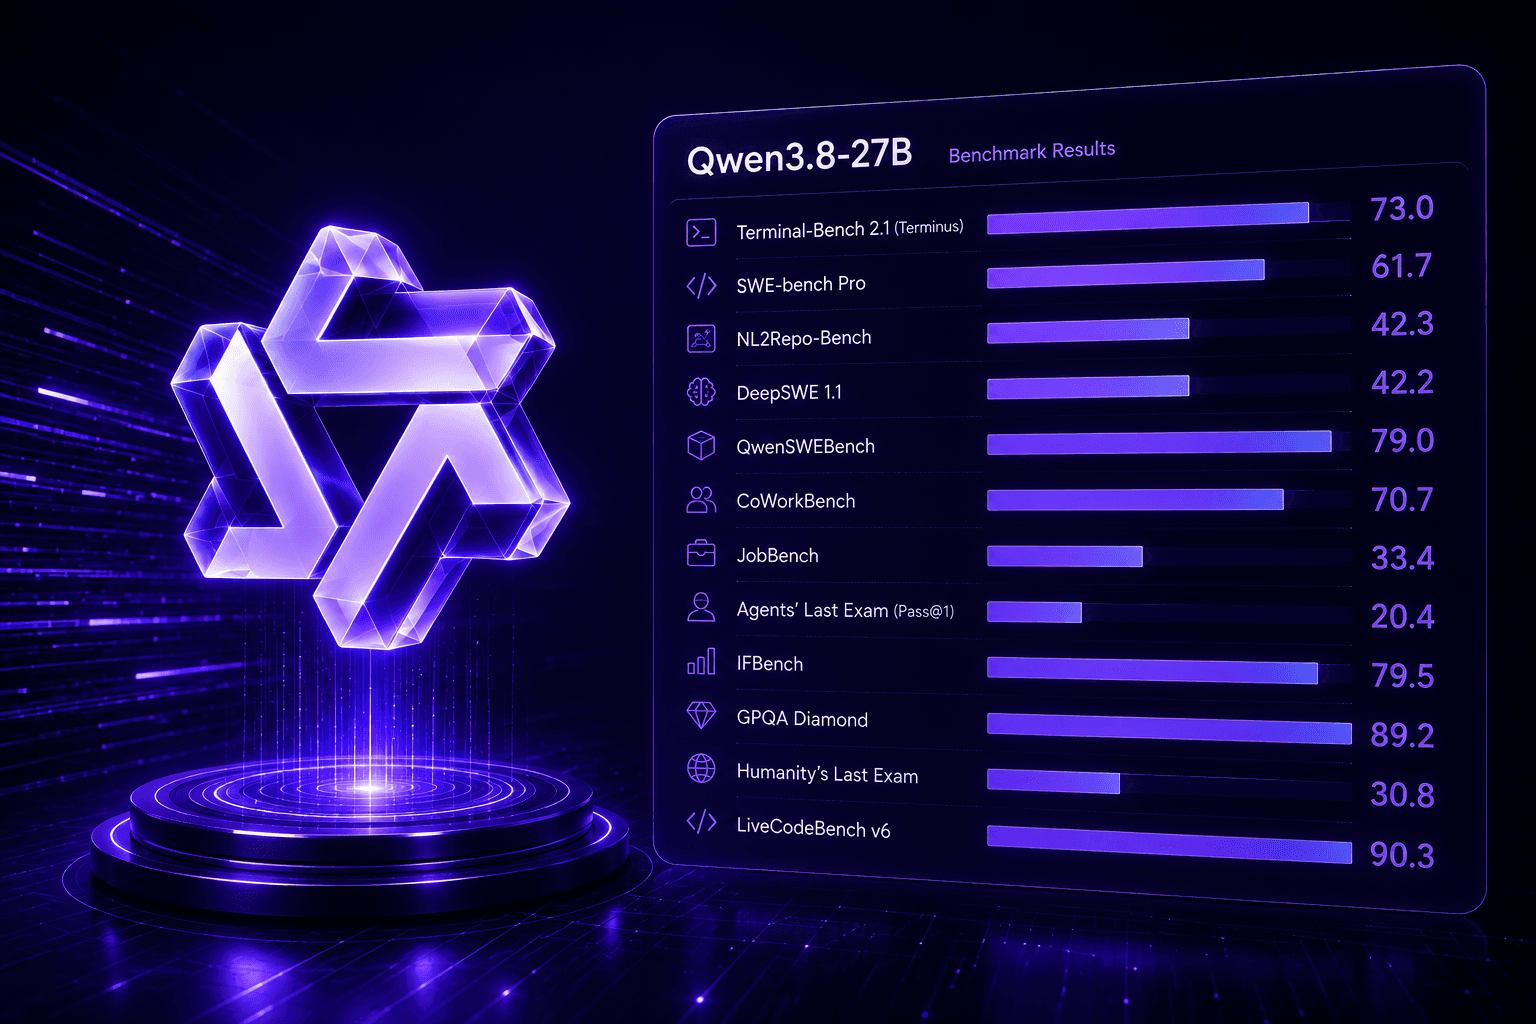
Qwen3.8-27B scores 52 on the Artificial Analysis Intelligence Index at maximum reasoning effort and 61.7 on SWE-bench Pro per Qwen's own evaluation. It leads its comparison set on agentic coding and computer-use benchmarks while trailing frontier models on Humanity's Last Exam and GPQA Diamond. Several headline numbers come from Qwen's internal evaluations, and this page labels which.
Official benchmarks: text performance
From the Qwen3.8-27B model card
Benchmark | Qwen3.8-27B | Qwen3.6-27B | Qwen3.7-Plus |
|---|---|---|---|
Terminal-Bench 2.1 (Terminus) | 73.0 | 63.4 | 64.0 |
SWE-bench Pro | 61.7 | 53.5 | 57.6 |
NL2Repo-Bench | 42.3 | 36.2 | 41.1 |
DeepSWE 1.1 | 42.2 | 13.3 | 14.2 |
QwenSWEBench | 79.0 | 49.3 | 59.2 |
CoWorkBench | 70.7 | 61.0 | 65.1 |
JobBench | 33.4 | 21.8 | 27.6 |
Agents' Last Exam (Pass@1) | 20.4 | 10.6 | 13.2 |
IFBench | 79.5 | 69.1 | 79.1 |
GPQA Diamond | 89.2 | 87.8 | 90.3 |
Humanity's Last Exam | 30.8 | 24.0 | 34.7 |
LiveCodeBench v6 | 90.3 | 83.9 | 89.6 |
Two things stand out. The generational jump on agentic coding is large: DeepSWE 1.1 moves from 13.3 to 42.2 and QwenSWEBench from 49.3 to 79.0 against the previous 27B. And the 27B beats the closed-weight Qwen3.7-Plus on most agentic and coding rows while trailing it on Humanity's Last Exam and GPQA Diamond.
That shape is consistent and worth internalising: this model converts its parameter budget into agentic and tool-use performance unusually well, and into broad frontier knowledge less well.
As VentureBeat noted in its coverage, in Qwen's published table the 27B beats the listed Claude Opus 4.6 Max result on SWE-bench Pro and LiveCodeBench, while Opus stays ahead on Terminal-Bench, GPQA Diamond and Humanity's Last Exam. VentureBeat also points out that some evaluations are internal and the harnesses are not identical across every comparison, which makes the numbers poor grounds for declaring a universal winner.
Official benchmarks: vision-language performance
Benchmark | Qwen3.8-27B | Qwen3.6-27B | Qwen3.7-Plus |
|---|---|---|---|
Computer use - OSWorld-Verified | 84.3 | 63.9 | 73.3 |
Browser use - WebArena-Verified | 64.8 | 48.8 | 55.3 |
Mobile use - AndroidWorld | 81.9 | 70.3 | 81.0 |
Application recreation - RecreationBench | 47.1 | 29.8 | 30.2 |
Multimodal SWE - SWE-MM | 38.6 | 25.7 | 30.0 |
Visual web development - Vision2Web | 62.9 | 45.0 | 42.1 |
Visual math - MathVision (with CI) | 94.6 | 85.1 (without) | 90.3 (without) |
General visual reasoning - BabyVision (with CI) | 85.6 | 28.9 (without) | 70.4 |
Chart analysis - CharXiv RQ (with CI) | 90.2 | 78.4 (without) | 85.9 |
Document intelligence - OmniDocBench 1.5 | 91.1 | 89.4 | 91.4 |
Real-world perception - RealWorldQA | 85.9 | 84.1 | 86.9 |
Embodied intelligence - ERQA | 65.5 | 62.5 | 69.8 |
OSWorld-Verified at 84.3 against 63.9 for the previous generation is the headline. Computer-use agents were the weakest link in open multimodal models for most of the past two years, and a 20-point jump inside one generation at identical parameter count is a real result. WebArena-Verified moving from 48.8 to 64.8 says the same about browser automation.
Independent benchmarks: Artificial Analysis
The picture changed when Artificial Analysis indexed the model. Unusually, they evaluated each reasoning setting as a separate entry, which makes the quality-versus-verbosity trade-off legible in a way it rarely is.
Setting | Intelligence Index | Output tokens across the index | Peer median | Speed |
|---|---|---|---|---|
| 52 | 160M | 48M | Notably slow |
| 44 | 75M | 45M | Notably slow |
35 | 26M | 17M | 53.1 t/s |
Intelligence Index v4.1.1 is a nine-evaluation composite: GDPval-AA v2, τ³-Banking, Terminal-Bench v2.1, SciCode, Humanity's Last Exam, GPQA Diamond, CritPt, AA-Omniscience and AA-LCR.
The 52 at xhigh is the number that circulated. As Simon Willison noted when the score landed, it matched GPT-5.6 Luna at maximum reasoning and sat one point behind GLM-5.2 and DeepSeek V4 Pro at max, both vastly larger mixture-of-experts systems.
The reaction from the open-source tooling community explains why it registered. The team behind the Cline coding agent posted: "This is the first time a local model has scored frontier model capability."
The generational comparison
Artificial Analysis also tracks the predecessor. Qwen3.6-27B scores 38 on the Intelligence Index in reasoning mode.
That is a 14-point jump at identical parameter count. Diff the two config files and the architecture is essentially unchanged: same 64 layers, same hidden size, same hybrid Gated DeltaNet layout, same max positions. Every point came from post-training - reinforcement learning environments and on-policy distillation. It is also why llama.cpp supported the model on day one.
The Agentic Index, and a number that gets misquoted constantly
Artificial Analysis publishes a separate Agentic Index measuring tool-use and multi-step task performance. Qwen3.8-27B scores 50.877, displayed as 51, placing it above Claude Opus 4.8 at maximum reasoning effort.
Three corrections, because most coverage gets these wrong:
52 and 51 are different measurements. 52 is the Intelligence Index. 51 is the rounded Agentic Index. Conflating them produces a better headline and a worse analysis.
The Agentic Index margins are narrow. The lead over the next model is under one point, and comparisons are between specific reasoning-effort variants, not entire model families.
The 27B ranks higher on Agentic than on Intelligence. Not a contradiction. It means the model converts a compact parameter budget into planning and tool-mediated workflow performance exceptionally well, without leading a broad knowledge suite.
The honest reading: a 27B dense open-weight model is now competitive with hosted frontier systems on agentic and tool-mediated work, while trailing them on the hardest frontier reasoning. That is a new position on the price-performance curve, and it is not the same claim as "beats Opus."
Independent benchmarks: structured extraction
Less discussed than the coding scores, and arguably more useful. Qwen3.8-27B was evaluated on LlamaIndex's ExtractBench, running the FP8 checkpoint under vLLM with one-shot structured output from files:
ExtractBench split | Score |
|---|---|
Mean | 89.75 |
Short documents | 94.68 |
Medium documents | 87.54 |
Combined with 91.1 on OmniDocBench 1.5, this makes a coherent case for a workload class that is not "coding agent": invoice and receipt parsing, form extraction, contract clause pulling, chart digitisation, screenshot-to-schema pipelines. Configuration for these tasks is in the API guide.
Methodology caveats you should actually read
The Qwen model card is unusually transparent about how its numbers were produced. Passing that along honestly:
Several benchmarks are in-house. QwenSWEBench, CoWorkBench and RecreationBench are Qwen's own internal evaluations. They are not independently reproducible.
The evaluation harness is not neutral across comparisons. SWE-bench Pro, NL2Repo-Bench, DeepSWE 1.1, QwenSWEBench, Vision2Web and SWE-MM were all evaluated using the Claude Code harness. Comparison models were re-evaluated on refined benchmarks, but harness choice affects agentic scores materially.
HLE was judged by GPT-4o. LLM-as-judge introduces its own variance.
MathVision used a fixed prompt for Qwen3.8-27B while comparison models got the better of two prompt variants.
Ground-truth corrections were applied. A small number of incorrect annotations in MathVision and CharXiv were manually corrected before scoring.
NL2Repo-Bench disabled network commands such as
pip installandgit cloneto prevent reward hacking.
None of this means the numbers are wrong. It means vendor benchmarks are vendor benchmarks until someone else reproduces them, which is exactly what the Artificial Analysis and ExtractBench results above did.
What the leaderboards do not capture
Tool calling holds up in a real agent loop. Willison pointed the model at a real codebase through a coding agent framework and it produced a correct explanation of the authentication architecture after a sequence of reasoning and file-reading tool calls, then wrote and tested a working Python utility in a follow-up session.
Visual grounding is strong. Asked for JSON bounding boxes on a 0-1000 normalised scale, the model returned coordinates matching the targets closely:
[
  {"bbox_2d": [195, 290, 370, 780], "label": "pelicans"},
  {"bbox_2d": [445, 320, 675, 850], "label": "pelicans"}
]
And the verbosity problem. Artificial Analysis flags the model as very verbose at xhigh - roughly 3.3x the peer median in output tokens. Willison measured a single SVG request consuming 22,276 reasoning tokens to produce 3,223 tokens of output. Developer and investor Tomasz Tunguz ran a nine-task comparison and found the model roughly 30x slower and 4.5x more expensive with reasoning on, cautioning that nine tasks is not a verdict. Benchmark scores at xhigh are real, but they are not free.
Adoption, which no index measures. Cybernews reported 3 million Hugging Face downloads in the first three days, and the r/LocalLLaMA megathread exists purely to consolidate community benchmark runs. Business Insider's analysis of Hugging Face usage data shows real deployment skews heavily toward smaller models regardless of what tops the leaderboards.
Frequently asked questions
What is Qwen3.8-27B's Intelligence Index score? 52 at xhigh reasoning effort, 44 at medium, 35 with reasoning disabled, per Artificial Analysis.
What does Qwen3.8-27B score on SWE-bench Pro? 61.7, per Qwen's own evaluation using the Claude Code harness at temperature 1.0 with a 256K context window.
What does Qwen3.8-27B score on GPQA Diamond? 89.2. This is one of the benchmarks where it trails frontier models rather than leading.
What does Qwen3.8-27B score on OSWorld? 84.3 on OSWorld-Verified, against 63.9 for Qwen3.6-27B and 73.3 for Qwen3.7-Plus.
Does Qwen3.8-27B beat Claude Opus? On specific measures, yes. It places above Claude Opus 4.8 on the Artificial Analysis Agentic Index by under one point, and above the listed Opus 4.6 Max result on SWE-bench Pro and LiveCodeBench in Qwen's own table. On Humanity's Last Exam, GPQA Diamond and Terminal-Bench, Opus leads. Narrow benchmark wins are not model equivalence.
Are Qwen3.8-27B's benchmarks independently verified? Partly. The Artificial Analysis Intelligence and Agentic Index scores are independent, as is the LlamaIndex ExtractBench result. QwenSWEBench, CoWorkBench and RecreationBench are Qwen's internal evaluations and have not been reproduced externally.
How does Qwen3.8-27B compare to Qwen3.6-27B? 52 versus 38 on the Intelligence Index, at identical parameter count and near-identical architecture. The gains came from post-training rather than scale.
Why does Qwen3.8-27B generate so many tokens? It defaults to xhigh reasoning effort. Artificial Analysis measured 160M output tokens across its index at that setting against a 48M peer median.
Benchmark it yourself
Qwen/Qwen3.8-27B is live on Qubrid AI at $0.58 per 1M input tokens. Point any OpenAI-compatible SDK at https://platform.qubrid.com/v1 and evaluate it on your own workload, which is the only benchmark that decides anything.

